Allow the Vizzybl crawler through your robots.txt, firewall, or WAF so site indexing returns pages, not zero.
Last updated
Vizzybl crawls your website to build the content index behind brand defense and content optimization. When our crawler can't read your pages, indexing returns 0 pages and a "needs attention" warning appears in Brand Protection → Content Index. This is Vizzybl's own crawler — not the Google or Vertex AI bot — so allow it explicitly using the details below.
Open Brand Protection → Content Index. A domain that couldn't be indexed shows one of two states:
robots.txt tells automated crawlers to stay out, so we didn't crawl. Nothing is broken; change the robots rule if you want us to index the site.Note: A 0-page result is not always a block. An over-broad rule in your
robots.txtcan hide almost every URL from every crawler — check that section below before assuming a firewall problem.
You can't edit a competitor's robots.txt or firewall, so the guidance on this page won't help there. When a competitor's site refuses our crawler but its robots.txt does not ask crawlers to stay away, the warning offers Try another way — an alternative fetch route that reaches some sites our own crawler cannot.
It is not guaranteed, and it usually returns fewer pages, so a result from it is labelled Limited coverage. It is available on Pro and above, and it costs the same credits as a normal index (see below).
If the competitor's robots.txt does ask crawlers not to index the site, we don't offer it. That is a stated preference and we respect it.
Indexing is metered on the pages we actually fetch, not the scan size you pick:
| Pages fetched | Credits |
|---|---|
| 1 | 1 |
| 20 | 10 |
| 100 | 50 |
| 1,000 | 275 |
The rate is 0.5 credits per page, dropping to 0.25 per page beyond 100. Three things are always free:
Re-indexing is therefore cheap: a weekly re-index of a 100-page site that changed three pages fetches three pages and costs 2 credits, not 50.
Vizzybl crawls from a single, stable egress IP. Allowlisting that IP in your firewall or WAF is the most reliable option, because our crawler falls back to a standard browser User-Agent for compatibility — so User-Agent matching alone may not catch every request.
Add this IP to your allowlist:
35.202.121.22
Important: Allowlist by IP as your primary rule, and add the User-Agent rule below as a second signal.
Using Cloudflare? Follow Allow Vizzybl in Cloudflare, step by step below. It takes about two minutes.
Cloudflare can refuse or silently drop our crawler, even when your site loads normally in a browser. When that happens, indexing times out and returns 0 pages. One custom rule that skips Cloudflare's security checks for our IP fixes it.
In the Cloudflare dashboard, open your domain and go to Security → WAF → Custom rules, then click Create rule.
Give it a name you'll recognise, for example Allow Vizzybl crawler.
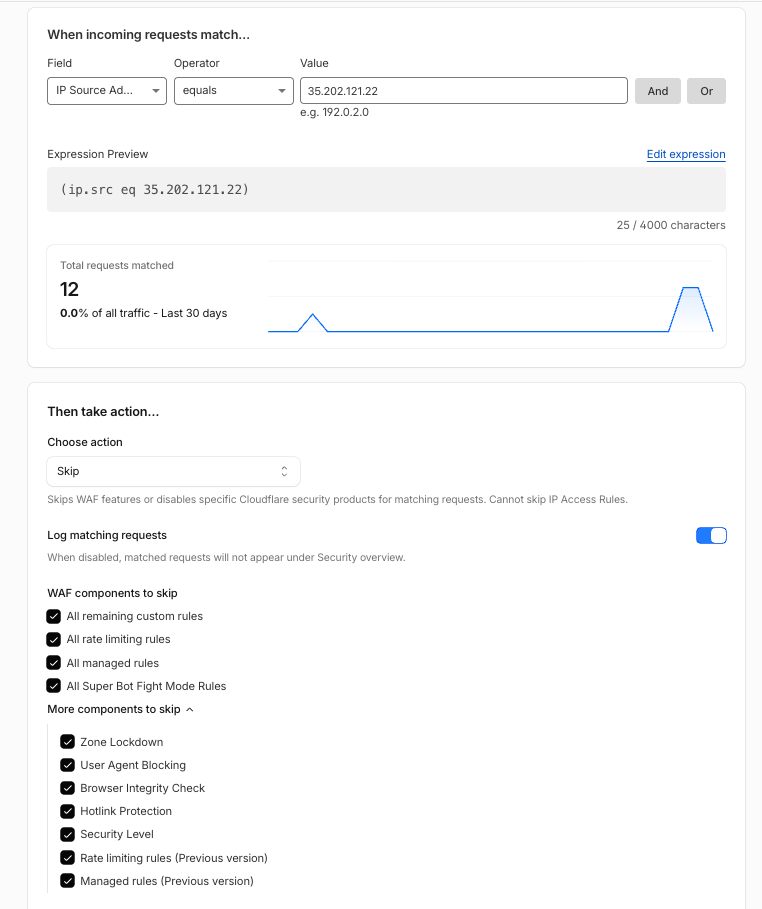
Under When incoming requests match…, set:
35.202.121.22The expression preview should read (ip.src eq 35.202.121.22). The Total requests matched panel shows whether we've already tried to reach your site.
Under Then take action…, choose Skip.
Leave Log matching requests on, so you can confirm the rule works.
Under WAF components to skip, tick all four:
Open More components to skip and tick all seven:
Click Deploy, then drag the rule to the top of your custom rules list. Skip only bypasses the rules that come after it.
This rule only matches traffic from Vizzybl's crawler IP, so it doesn't weaken protection for anyone else.
Important: Two Cloudflare features can't be bypassed by a Skip rule:
- Bot Fight Mode (the free version, under Security → Bots). If it's on, turn it off, or upgrade to Super Bot Fight Mode, which the rule above does skip.
- IP Access Rules (under Security → WAF → Tools). If you block or challenge Google Cloud or "hosting" networks there, add an IP Access Rule that Allows
35.202.121.22.
Check it worked: open Security → Events, filter by the IP address 35.202.121.22, and re-run your index. Events should show your new rule with the action Skip, and the index should report pages instead of 0.
Our crawler identifies itself on its first request to each page as:
Mozilla/5.0 (compatible; VizzyblBot/1.0; +https://vizzybl.ai/bot)
Allow it in two places:
User-agent: VizzyblBot
Allow: /
VizzyblBot. Managed bot-fighting rules often challenge unfamiliar crawlers, so name us explicitly.Note: User-Agent allowlisting is best-effort — if a site blocks
VizzyblBot, our crawler retries as a browser so indexing still works where it can. The IP rule above is the deterministic one.
Vizzybl honors robots.txt on every request, whatever User-Agent we send. An over-broad rule silently removes your content from indexing.
Warning: A rule like
Disallow: /*?blocks every URL that contains a query string. If your pages live on query-parameter URLs — common on booking, search, and catalog sites — this hides them from all crawlers. Add anAllow:for the paths Vizzybl should read, or scope theDisallowmore narrowly.
When both a wildcard group (User-agent: *) and a User-agent: VizzyblBot group are present, the VizzyblBot group takes precedence for us — so a specific Allow: / for VizzyblBot overrides a broad wildcard Disallow.
VizzyblBot (and our egress IP) return 200.